AI
Text summarisation service
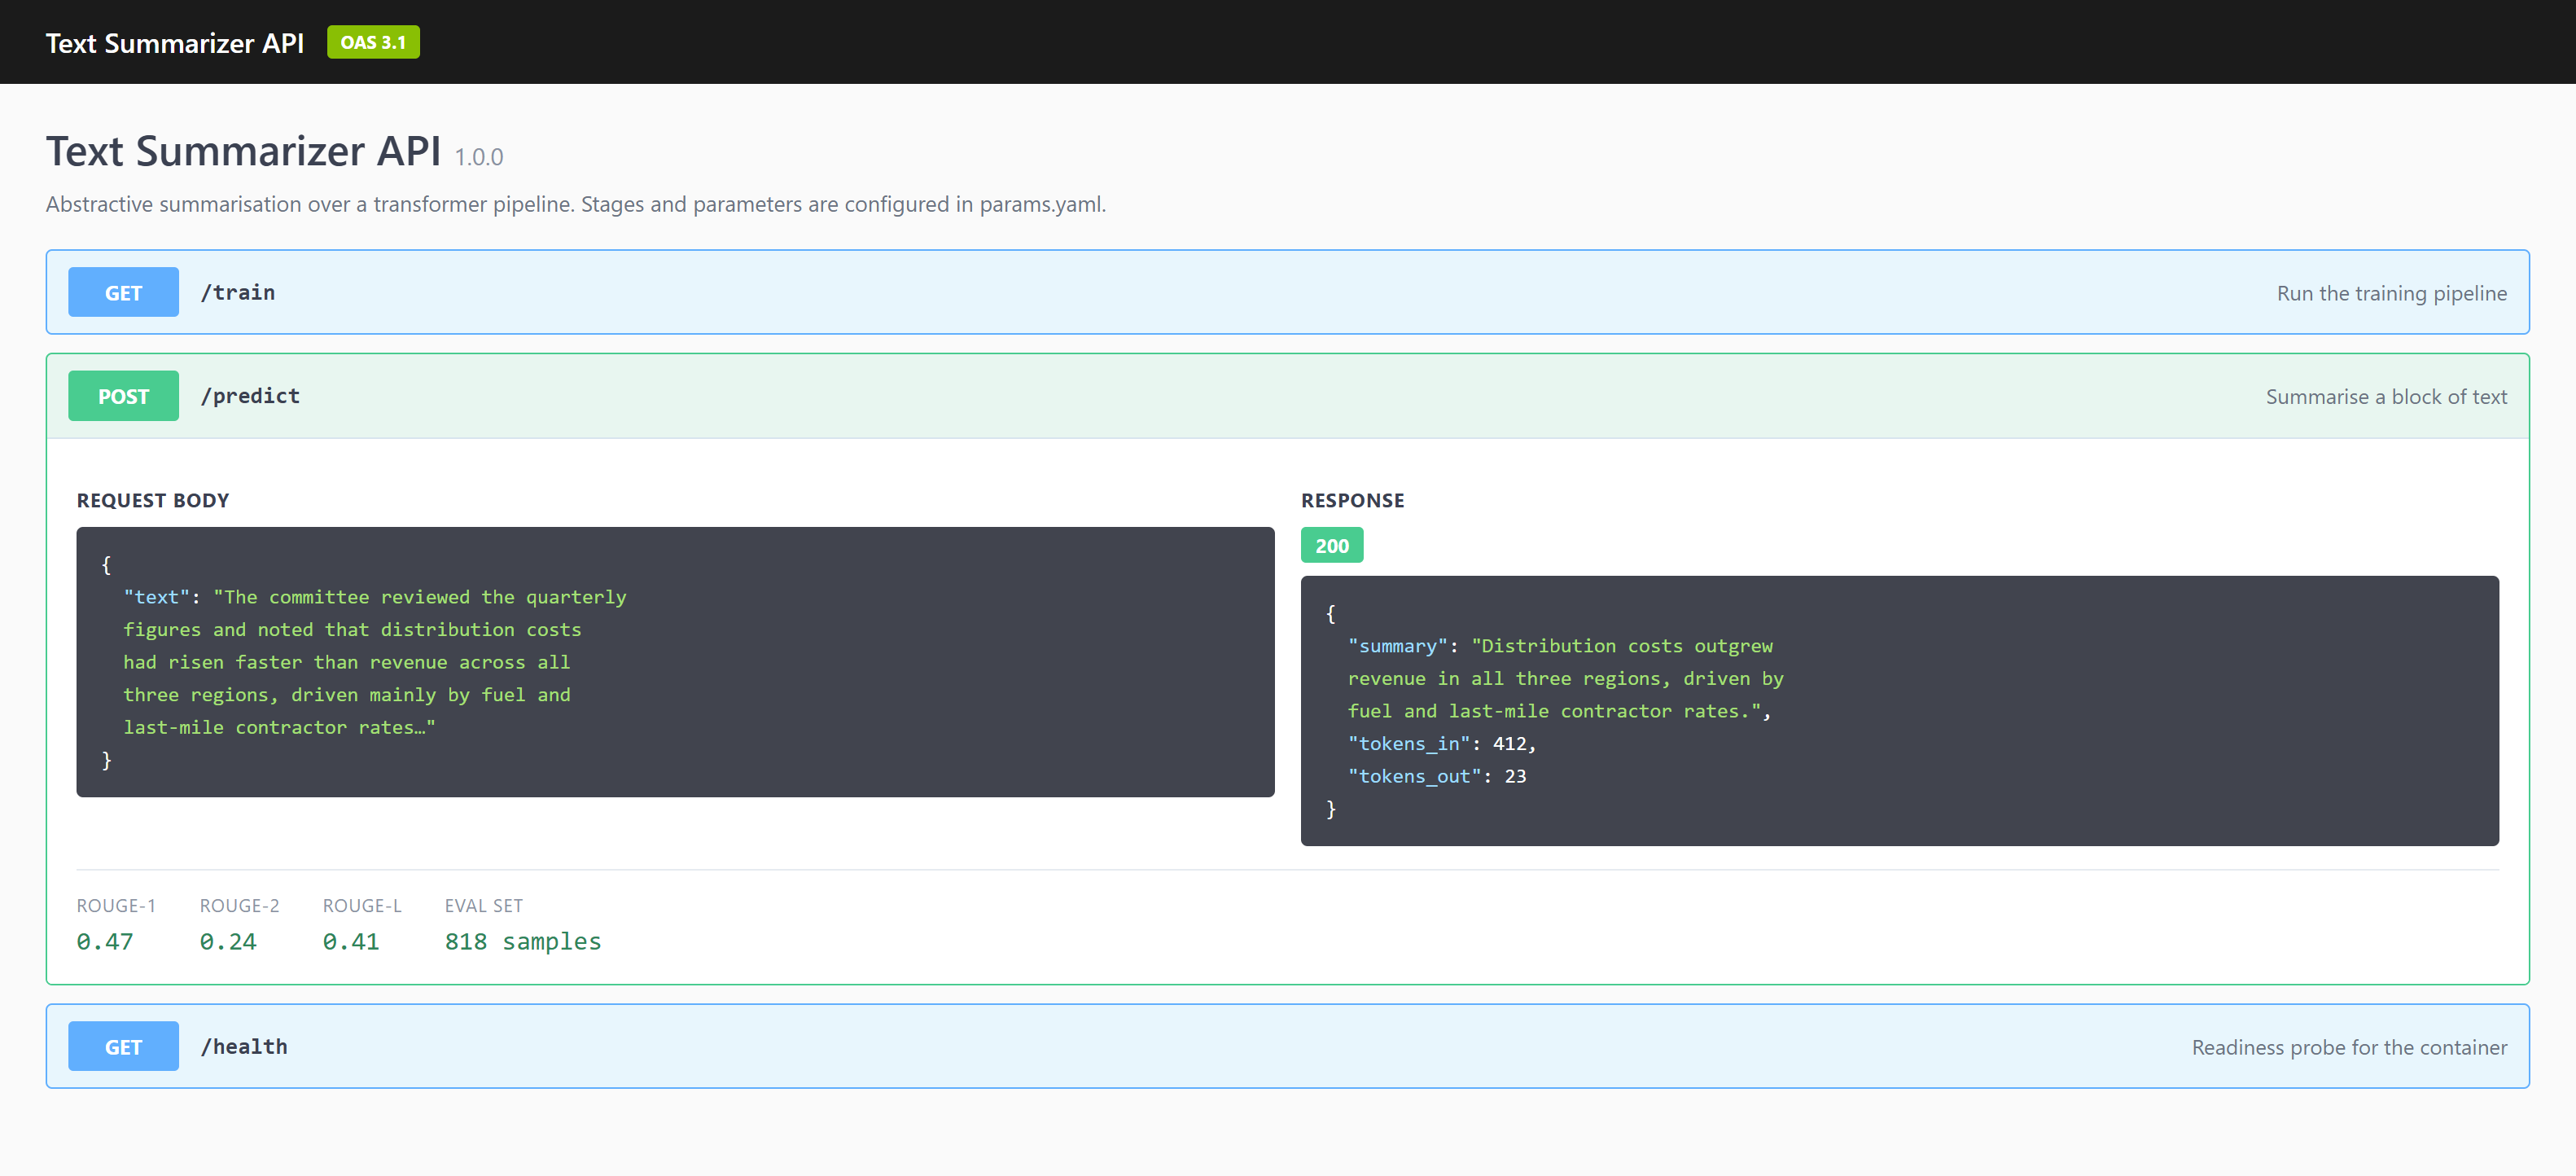
An abstractive summarisation pipeline built on transformer models, packaged behind an API and containerised for deployment.
Own buildTeam build
01The problem
What it had to solve.
Summarisation is easy to demo in a notebook and awkward to ship. The work is in the pipeline around the model — configuration, staged processing, evaluation and a deployable package.
02The build
How it was put together.
- Pipeline split into discrete stages, with configuration and parameters held in YAML rather than hardcoded
- Hugging Face transformers for the model, with datasets handling corpus preparation
- ROUGE scoring wired in, so summary quality is measured rather than eyeballed
- FastAPI serving layer exposing the pipeline as an endpoint
- Dockerfile and S3 integration, so the same image runs locally and on a server
Stack
TransformersPyTorchFastAPIDockerAWS S3
What it demonstrates
- An ML project laid out as a deployable application rather than a notebook
- Evaluation treated as part of the build, not an afterthought
- Configuration separated from code, so retraining does not mean editing Python
Next step
Tell us what you are trying to build.
A first call is thirty minutes, costs nothing, and ends with a straight answer about whether we are the right group for it — plus the names of the specialists who would actually do the work.